
A human response to synthetic respondents
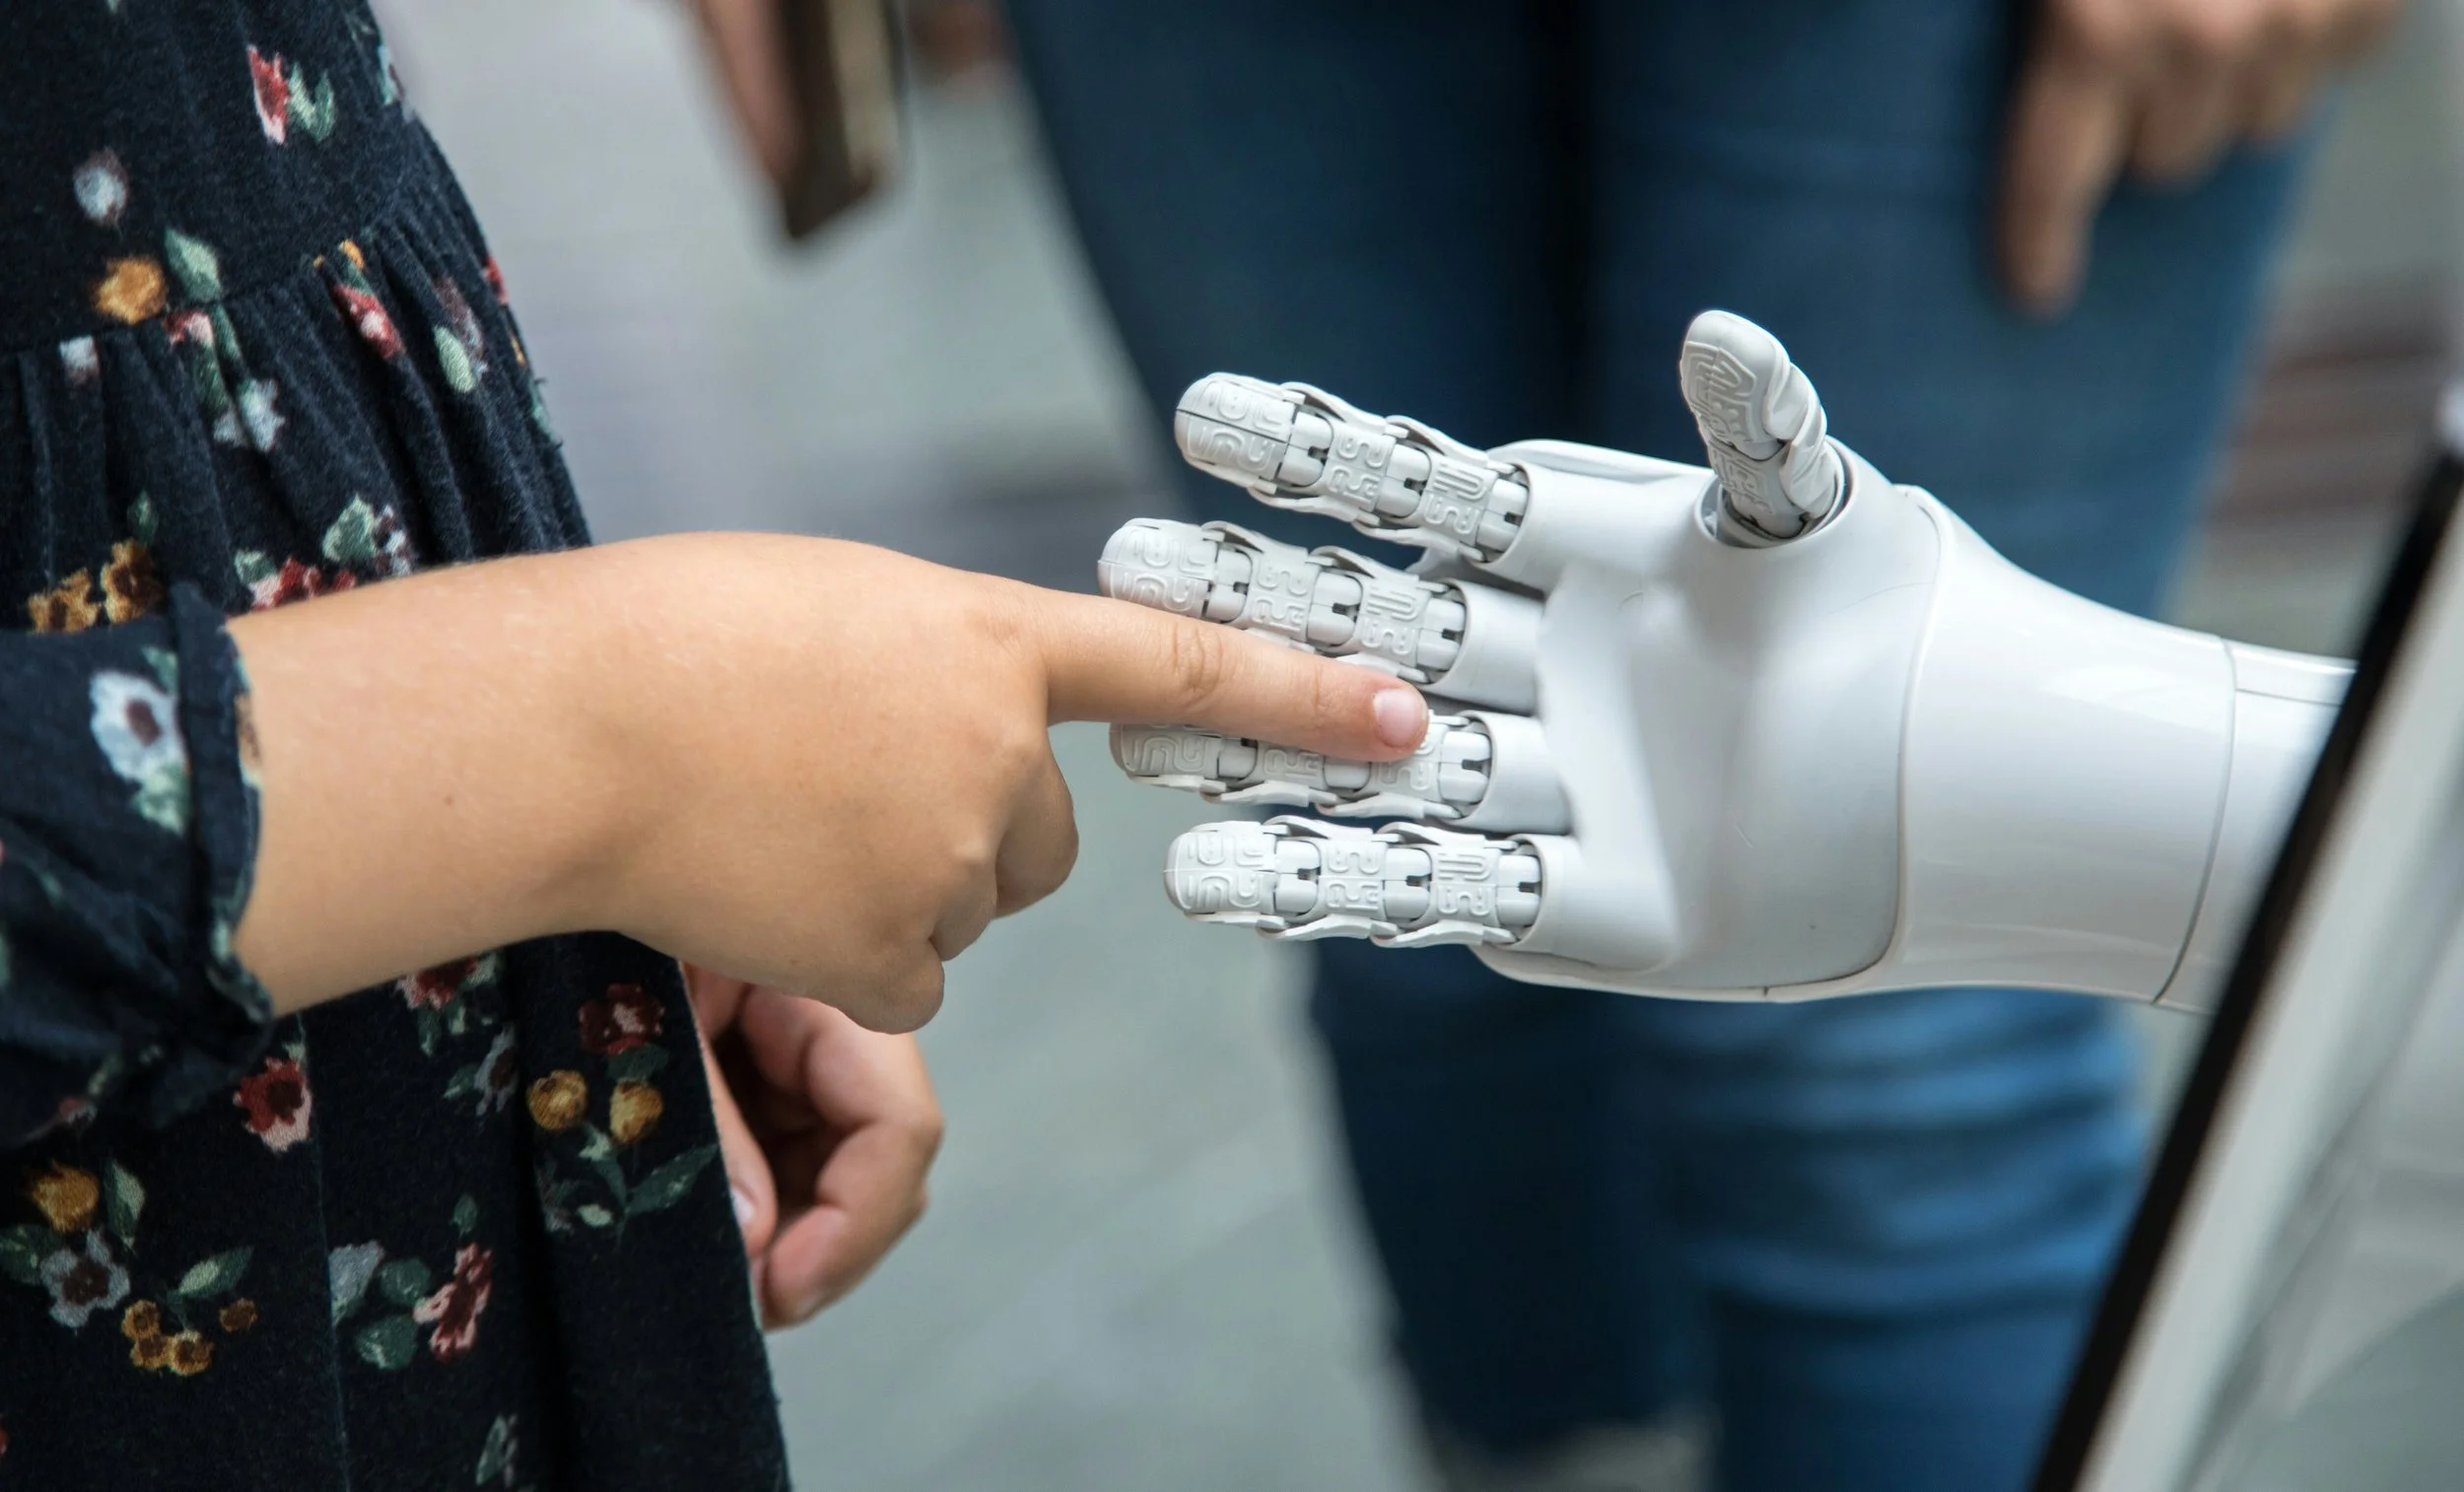
Credit: Katja Ano (Unsplash)
In common with every other area of our lives, AI is radically reshaping the market research sector. The scale and speed of change is mind-boggling. Last December, Claude conducted 80k individual depth interviews[1] in 70 languages in just one week. Everyone with a Claude.ai account was asked to sit down with Anthropic Interviewer — a version of Claude prompted to conduct a conversational interview — and talk, ironically enough, about their hopes and fears for AI.
This example was a survey of real people across the globe. Things have moved on apace and now the debate centres around not only the use of AI interviewers, but the use of synthetic respondents. Synthetic respondents are AI-generated personas, powered by large language models, that take part in research as though they were real people. This idea is clearly extremely seductive to agencies selling the service and – to end clients – the ability to provide survey results in hours rather than weeks at a fraction of the cost is clearly gold dust. Furthermore, because the responses are simulated, the argument goes that researchers can explore sensitive topics or test unreleased concepts without the risk of leaks or compliance concerns. Qualtrics Edge, backed by findings from the company’s MR Trends study[2] make the case that synthetic data is “no longer a fringe innovation. It’s a foundational shift”.
Developments are prompting extensive debate across the industry[3], with some of the pressing issues encapsulated in an MRS podcast which explores the case for using synthetic data from legal, ethical, methodological and financial perspectives. One of the big questions is who is ensuring that synthetic respondents are being used responsibly and that clients are kept informed.
There are also some fundamental questions being asked about the reliability of data derived from synthetic respondents. Some have conducted experiments which have compared synthetic sample with human responses. For example, Kantar[4] have found that the synthetic respondents seem to be overly positive compared to the human survey respondents. On a practical question about the price of a product, the synthetic sample’s responses are aligned more closely to human responses. But on the questions that require a little more thought (emotion connected to using the product, for example), there is much greater deviation.
User Intuition[5] conducted depth interviews on mental load and AI assistants with around 100 human respondents. They ran the same interview guide through Claude, GPT-5.3, and Gemini — assigning ten structured personas at three iterations per persona per model, for 90 synthetic interviews in total. They found that “synthetic participants do not primarily fail by giving absurd answers. They fail by giving answers that are too co-operative, too coherent and too close to the model thesis of the study”.
All of this has got us thinking about the use of synthetic respondents for qualitative research. They are increasingly part of the picture - from use in piloting survey questions, to the generation of broad personas and synthetic interviews.
We have real reservations for their application for the type of research that we do. Clearly, synthetic respondents or personas are only as good as data on which they are based. Many of the individuals we engage with are seldom represented in research and are, in many senses, marginalised in society. How can we be sure that their views and experiences feature in the data which is already out there? In many cases, they are not and that is why we are being asked to research their views. How will the models then create synthetic personas which capture their experiences? There is a high risk that any representations will be stereotypical, without nuance and will not reflect cultural norms. Furthermore, the use of this technology risks these audiences being further marginalised.
And what about its use with those individuals who are not living in vulnerable circumstances? We agree with much this article from The Qualitative Researcher[6], and in particular the argument that a fundamental limitation is that it cannot effectively capture the essence of lived experience — “qualitative research is built on the premise that human experience is irreducible — that understanding what it means to live with chronic pain, to navigate institutional racism, or to lose a child requires actually talking to people who have lived those experiences. An AI model can produce text that resembles what a grieving parent might say. It cannot grieve.”
In short, whilst AI innovation clearly has a place, we are very mindful of its risks and shortcomings. We feel strongly that technological developments make what we do at Community Research — engaging with real people using human interviewers — more, and not less, important.
[1] https://www.anthropic.com/features/81k-interviews
[2] 2026 Global Market Research Trends Report - Qualtrics
[3] Using synthetic respondents for market research | Market Research Society
[4] What is synthetic sample - and is it all it’s cracked up to be?
[5] Synthetic Mirage in Market Research | Real vs AI Participants
[6] Synthetic Data in Qualitative Research: Promise, Peril, and Practice | The Qualitative Researcher